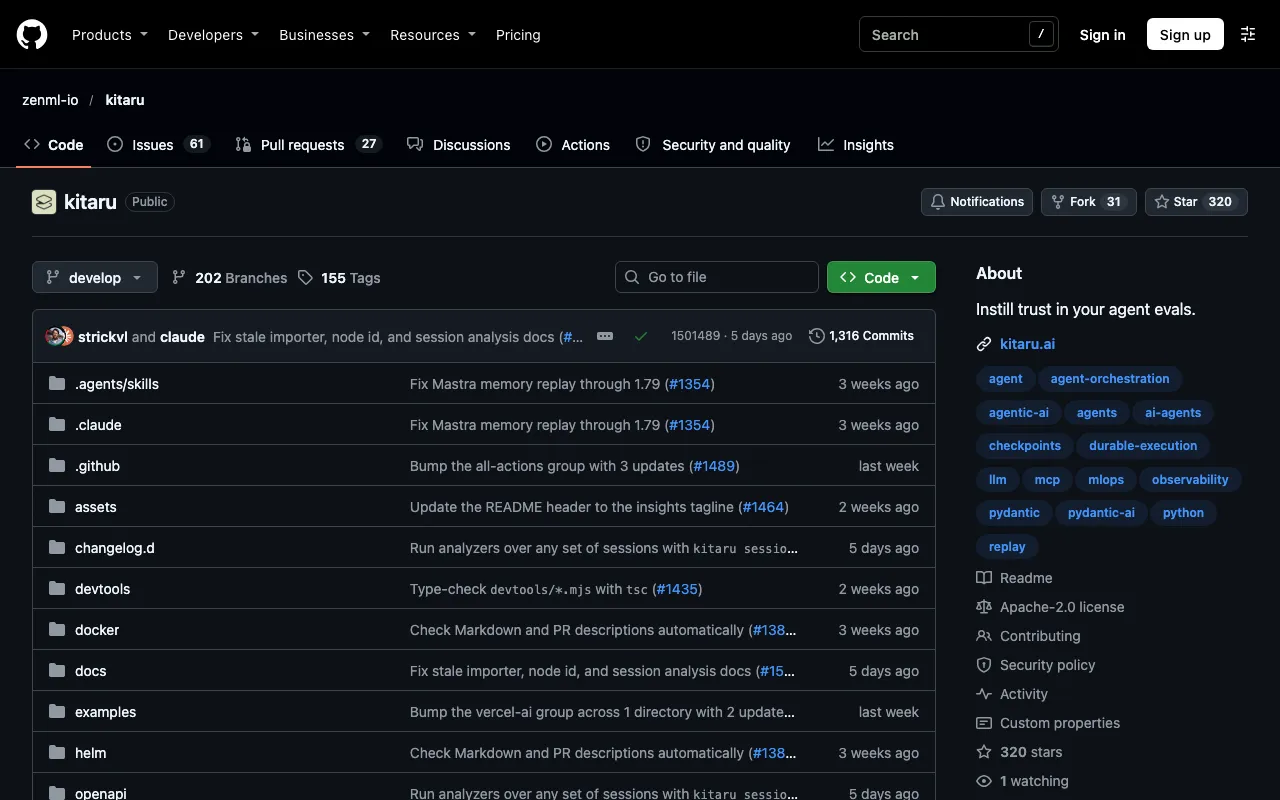
Instill trust in your agent evals
About Kitaru
Kitaru is ZenML's open-source durable execution layer for Python agents. It sits underneath an agent harness instead of replacing it: Pydantic AI, the Claude Agent SDK or the OpenAI Agents SDK keeps defining the agent loop, and Kitaru wraps it with checkpoints, replay, resume, wait states, artefacts, execution history and versioned deployments.
Completed checkpoints stay completed. After a failure, earlier model and tool calls are read back from saved state, the failed step runs again and execution continues. ZenML also says it records production runs and replays them as evals, to catch regressions, and Pydantic AI's documentation shows wrapping an agent with a Kitaru adapter.
Sources are mostly vendor material from ZenML and Pydantic, so the eval claims are not independently confirmed.
Key features
- Durable execution for Python agents
- Checkpoints, replay and resume
- Wait states for human input
- Replay of recorded runs as evals
- Adapter for Pydantic AI
- Works under agent SDKs from Anthropic and OpenAI
Links
All content and agents from Kitaru
Frequently asked questions about Kitaru
- What is Kitaru?
- Instill trust in your agent evals. It is listed on botshub under agent observability and evaluation.
- Where is Kitaru from?
- Kitaru comes from Germany.
- Is Kitaru free or open source?
- Kitaru is tagged as open source on botshub. Check the official site for current terms.
- What can Kitaru do?
- Key features include durable execution for Python agents, checkpoints, replay and resume, wait states for human input, replay of recorded runs as evals and adapter for Pydantic AI.
- What are alternatives to Kitaru?
- Other agent observability and evaluation on botshub include LangFuse, ClawMetry, Opik and OrcaReplay. See all alternatives to Kitaru.