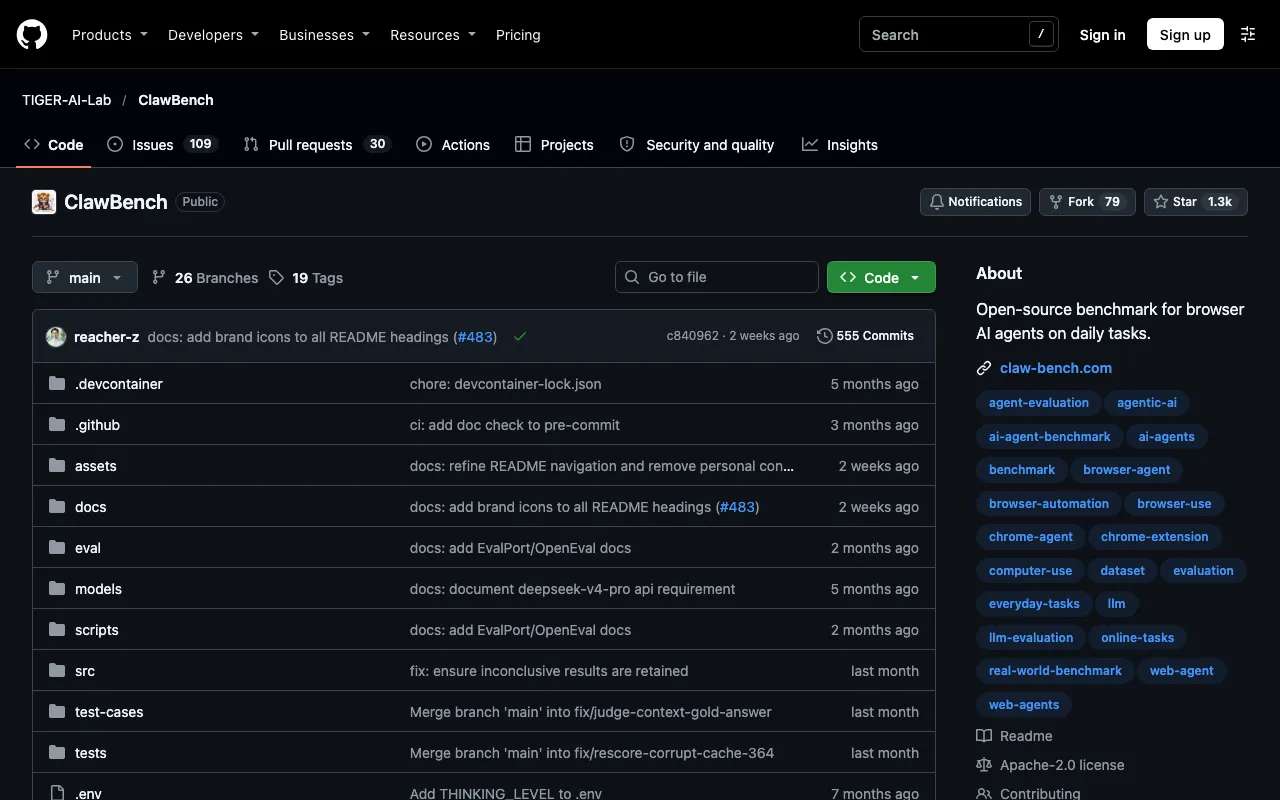
Open-source benchmark for browser AI agents on daily tasks.
About ClawBench
ClawBench is an open-source benchmark from TIGER-AI-Lab for testing browser agents on everyday tasks on live websites, described in the arXiv paper 2604.08523 with a leaderboard on Hugging Face. Tasks include ordering food, booking travel, applying for jobs and managing email.
The first suite has 153 tasks across 144 websites, a second adds 130 tasks, and a 20-task lite suite allows faster runs. Each run is isolated in Docker and records five layers of traces: video, action screenshots, network traffic, browser actions and agent messages. Grading combines DOM matching and a language model judge, and traces are published as Hugging Face datasets.
Reported top scores are low, about a third on the first suite and under 20 percent on the second, and the leaderboard changes as new models are added. The package installs from PyPI as clawbench-eval.
Key features
- Benchmark for browser agents on live sites
- 153 tasks across 144 sites in the first suite
- Docker-isolated runs
- Five layers of recorded traces
- DOM matching plus model judge
- Public leaderboard and datasets
Links
All content and agents from ClawBench
Frequently asked questions about ClawBench
- What is ClawBench?
- Open-source benchmark for browser AI agents on daily tasks. It is listed on botshub under other agents.
- Where is ClawBench from?
- ClawBench comes from Canada.
- Is ClawBench free or open source?
- ClawBench is tagged as open source on botshub. Check the official site for current terms.
- What can ClawBench do?
- Key features include benchmark for browser agents on live sites, 153 tasks across 144 sites in the first suite, docker-isolated runs, five layers of recorded traces and dOM matching plus model judge.
- What are alternatives to ClawBench?
- Other other agents on botshub include ChemCrow, Marvin, Moss and YouTube Skills for AI Agents. See all alternatives to ClawBench.